AI economics
The AI bottleneck has moved from intelligence to cost
For two years the honest answer to "can AI do this?" was often no. The model was not smart enough, so the work stopped there. That question has quietly stopped being interesting. On most business tasks a frontier model is now at least as good as a competent professional, and open-weight models a few months behind are good enough for a large share of the rest.
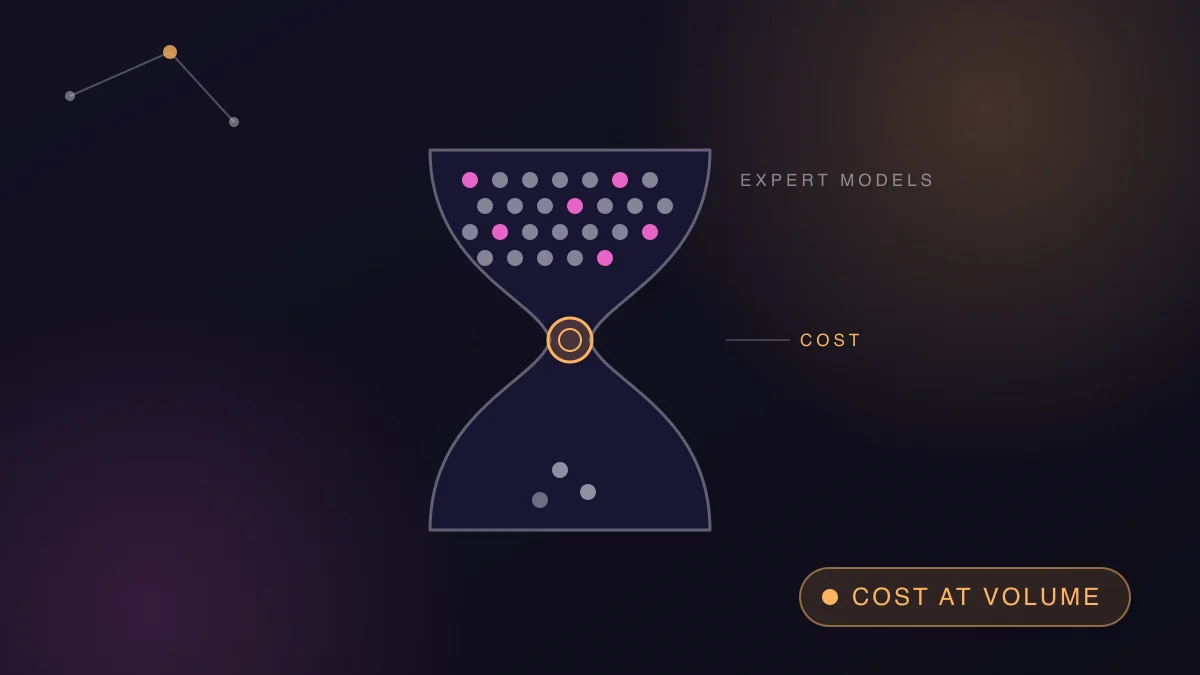
So the interesting question changed. It is no longer "is the model smart enough?" It is "can we run it, at our volume, every day, at a cost that beats the old way?" Intelligence stopped being the scarce input. Cost became the bottleneck, and cost is an engineering problem, not a model problem.
Capability overshoot is real
Watch what actually happens in a build now. The proof-of-concept works on the first afternoon. The model reads the contract, drafts the reply, classifies the ticket, extracts the fields. Nobody is impressed anymore; they expect it to work. The room does not fall apart over whether the model is capable. It falls apart over the invoice at production volume.
That is capability overshoot: the frontier is already past what most workflows need. Paying for the smartest possible model on every step is like flying a cargo 747 to deliver a single envelope. It arrives, beautifully, at a cost that makes the whole route uneconomic. The skill now is not summoning more intelligence. It is spending exactly as much as each step deserves and no more.
Where the cost actually hides
A system that looks cheap per query and turns out to cost a salary per month is almost never expensive for the reason people guess. The cost hides in the plumbing:
- The wrong model on trivial steps. Routing a yes-or-no classification to a frontier reasoning model, thousands of times a day, because it was easiest to wire that way.
- Context bloat. Stuffing the entire history into every call when a retrieved paragraph would do. You pay for those tokens on every single invocation.
- Silent retries and loops. An agent that fails, retries, second-guesses and re-plans burns tokens in proportion to its own confusion. Errors are not just accuracy problems; they are line items.
- No caching. Recomputing the same embeddings, the same system prompt, the same tool schema, forever.
- Humans reviewing everything. The most expensive reviewer is the one who reads output the system was already sure about.
None of these are fixed by a better model. Several get worse with a better model, because the smartest models are the most expensive per token and the most tempting to over-use.
The number that matters is not the monthly bill, it is cost per successful outcome:
Cost per successful outcome = (model calls + tool calls + retries + storage + human review) / successful outcomes
Before approving an AI workflow, ask for five numbers: cost per successful outcome, model calls per outcome, retry rate, human-review rate, and the cost delta between the current model mix and a tiered one.
How we engineer it down
The autonomous newsroom we run in production publishes long-form articles every day, and its cost per article is not a model choice. It is the sum of a dozen decisions about where money is allowed to go:
- Tier the models. Cheap and open-weight models do the volume: retrieval, classification, first-pass drafting, deduplication. Frontier models are reserved for the few steps where judgment genuinely pays for itself. Most calls in a well-built system never touch the flagship.
- Discipline the context. Retrieve the few passages that matter instead of paying to re-read everything, every time.
- Cache the boring parts. Prompts, schemas and embeddings are computed once, not per request.
- Budget the agents. Every job has a token ceiling and a retry cap, so a confused agent fails loudly and cheaply instead of quietly spending all night.
- Route by confidence, not by default. People review the uncertain slice, which is where their attention is worth paying for, not the nine cases in ten the system already got right.
Where the cost hides, and what brings it down
| Where the cost hides | How it is engineered down | |
|---|---|---|
| Model choice | A frontier reasoning model on trivial yes-or-no steps | Cheap and open-weight models do the volume; frontier models only where judgment pays |
| Context | The entire history stuffed into every call | Retrieve the few passages that matter |
| Retries and loops | A confused agent retries and re-plans, burning tokens | A token ceiling and a retry cap on every job |
| Caching | The same embeddings, system prompt and tool schema recomputed forever | Prompts, schemas and embeddings computed once |
| Human review | People read output the system was already sure about | People review the uncertain slice, routed by confidence |
Where the cost hides
- Model choice
- A frontier reasoning model on trivial yes-or-no steps
- Context
- The entire history stuffed into every call
- Retries and loops
- A confused agent retries and re-plans, burning tokens
- Caching
- The same embeddings, system prompt and tool schema recomputed forever
- Human review
- People read output the system was already sure about
How it is engineered down
- Model choice
- Cheap and open-weight models do the volume; frontier models only where judgment pays
- Context
- Retrieve the few passages that matter
- Retries and loops
- A token ceiling and a retry cap on every job
- Caching
- Prompts, schemas and embeddings computed once
- Human review
- People review the uncertain slice, routed by confidence
None of these is fixed by a better model. The number to watch is cost per successful outcome: model calls, tool calls, retries, storage and human review, divided by successful outcomes.
Do this and the same workload that was genuinely unaffordable a year ago runs at a fraction of the price, with the quality unchanged. Skip it and you will blame the model for a bill the architecture created.
Why this is good news
Falling cost is not a threat to the work; it is what makes the work possible. The problems worth automating were always the ones with real volume, and volume is exactly where cost used to make the math fail. Two years ago you could not buy the thing. One year ago you could not afford to build it. Now it is a scoped engagement, because the price of running intelligence has collapsed and is still falling.
That also means the durable advantage is no longer "we have access to a smart model." Everyone has that. The advantage is knowing where every dollar and every token goes, and building the system so it goes to the right place. That is unglamorous engineering, and it is the whole game now.
If you are evaluating an AI build, stop asking whether the model is clever. Ask for the cost per outcome at your real volume, ask which steps run on cheap models and which on expensive ones, and ask for the story of how they took a workload that was too expensive and made it cheap. A team that cannot answer has not run anything at scale.