Insights
Written from production, not from theory.
What we learn running agentic systems, AI employees and human-in-the-loop operations for real businesses. New notes every week.
Get new Insights posts
New Insights posts by email, at most once a week. You confirm by email first, and every email has an unsubscribe link. How we handle your email
 Security
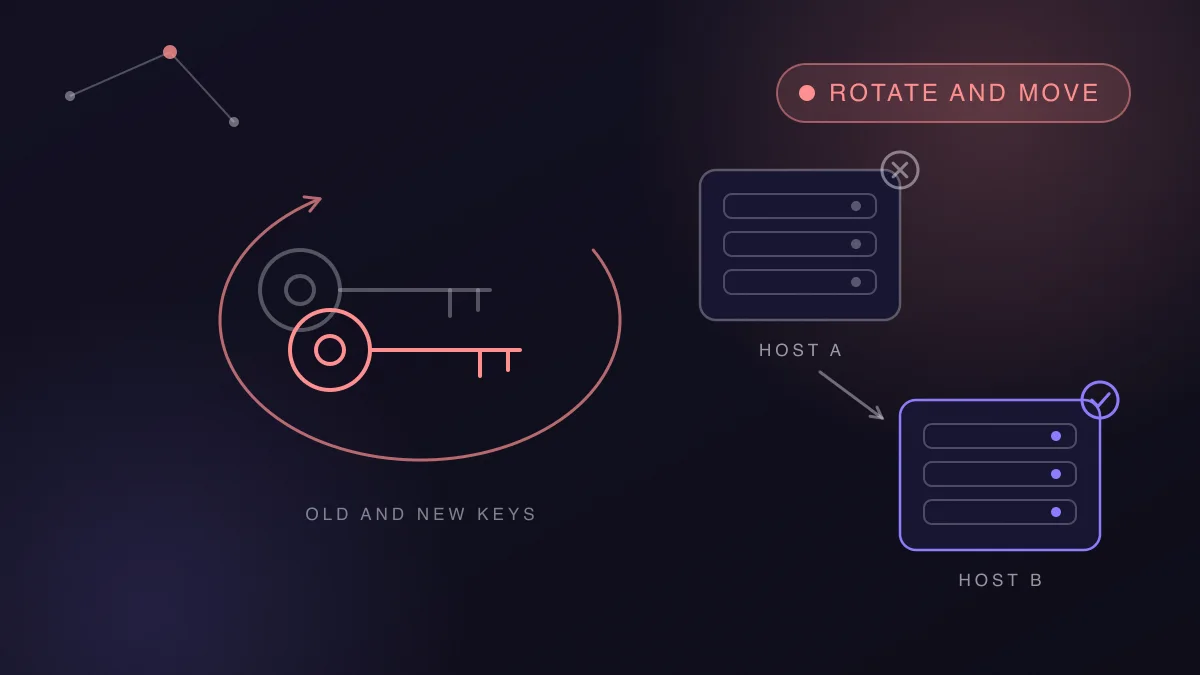
Make a provider breach a drill: rotate keys, swap certificates, move hosts
eMudhra and Railway left their customers the same jobs. How to make rotating secrets, swapping certificates and moving production routine.
 22 Oct 2026 · 7 min read
 Agentic AI
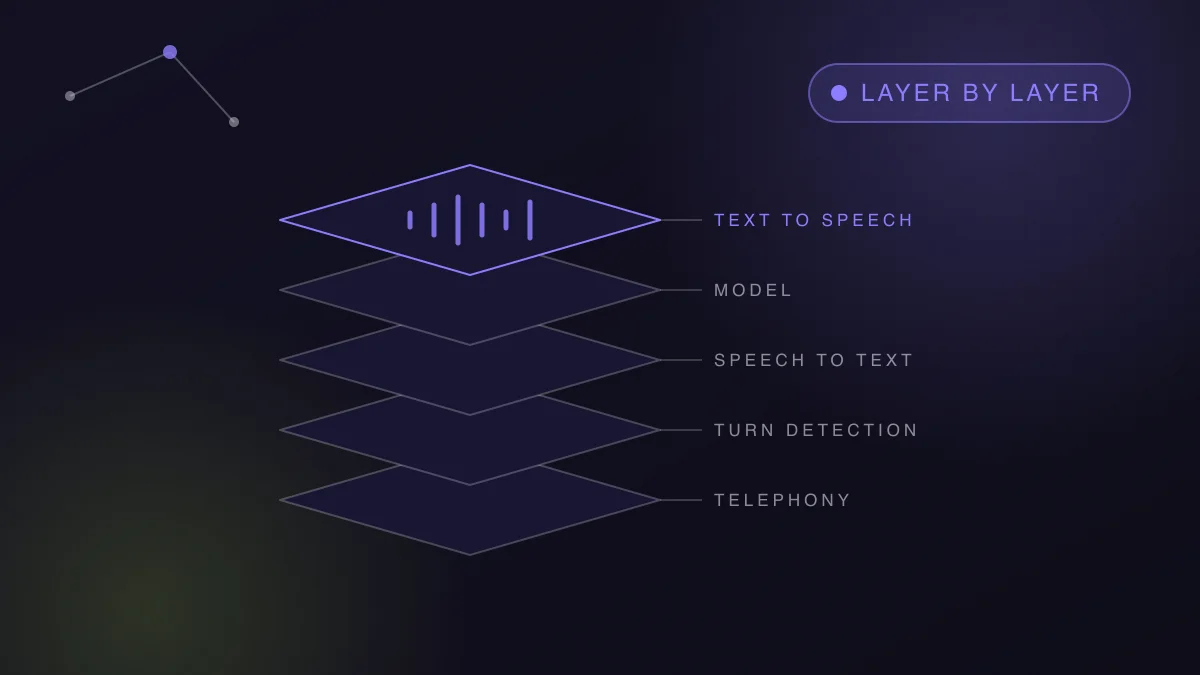
The voice agent stack, layer by layer, and what to test in each
Telephony, turn detection, speech to text, the model and text to speech, or one speech to speech model. The main tools in each layer and how to choose.
 19 Oct 2026 · 12 min read
 Buying guides
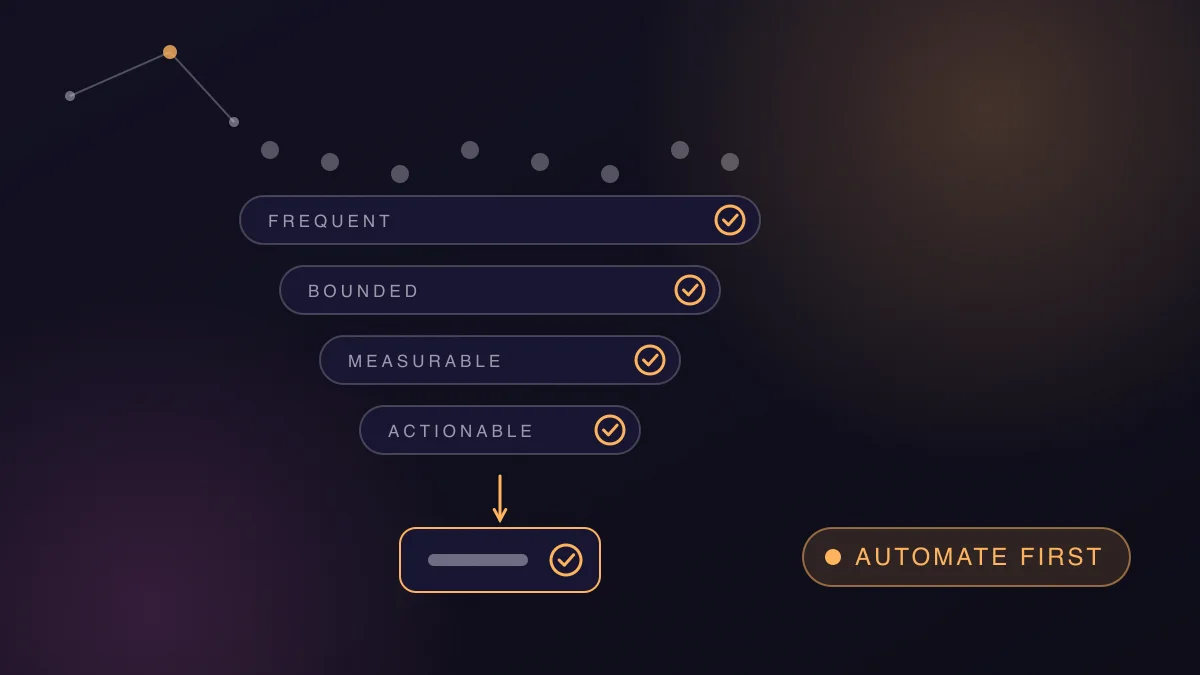
Automate work that is frequent, bounded, measurable and actionable
A four-question filter for what to hand to an AI agent first, written for teams without engineers, with a self-check to run on any task.
16 Oct 2026 · 10 min read Evals and accuracy
India is the hardest test for a voice agent
Code-mixed speech, many languages, narrowband phone lines and strict calling rules. The Indian tools, including Sarvam and AI4Bharat, and a readiness check.
 15 Oct 2026 · 14 min read
 Evals and accuracy
How to test a voice agent with simulated callers and native speakers
Simulated callers catch regressions at volume. Native speakers on real phones catch accents, noise, tone and drift. A practical plan that uses both.
13 Oct 2026 · 12 min read Agentic AI
What a forward deployed engineer does, and how to tell if you are ready
An FDE is judged by what still runs in the client's operations after handover. This post explains the job and gives a 12-question readiness test.
11 Oct 2026 · 11 min read Buying guides
Data licenses for AI. Name the level before you pick the model.
We propose six open, SPDX-style levels that say which AI deployments may use a dataset. Name the level first and the model shortlist follows.
10 Oct 2026 · 11 min read Buying guides
What AI providers' data terms allow. Choose the deployment, then the model.
The same model can be safe or off-limits for the same data, depending on the route. We map seven AI deployment types to the six AI Data Levels.
10 Oct 2026 · 11 min read Evals and accuracy
Benchmarks stopped predicting which model works. Here is what we use instead.
Every Claude launch from Sonnet 4.6 to Opus 5.5 posted higher scores. Why public benchmarks stopped predicting real work, and how we choose a model.
9 Oct 2026 · 11 min read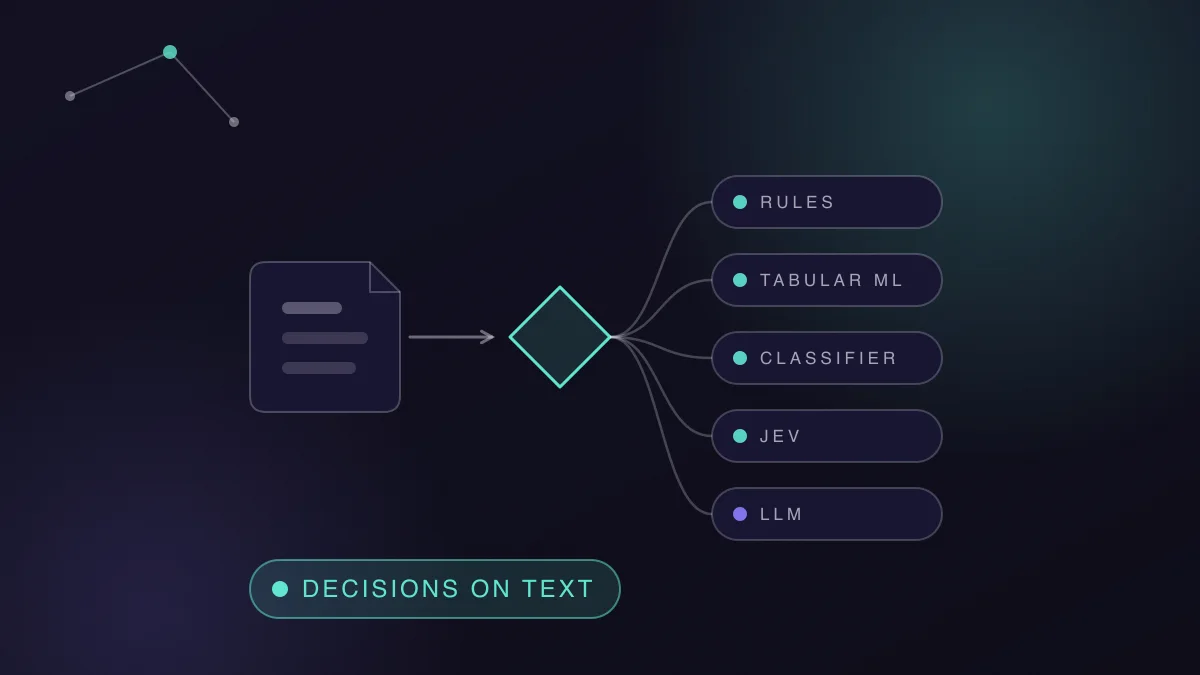 Buying guides
When to use Jev, an LLM or traditional machine learning
Most AI calls in a product are decisions on text. When to use rules, tabular ML, a trained classifier, Jev or an LLM, and how to test each.
8 Oct 2026 · 11 min read Frontier AI
AI to SI. Measure the loop, not the date.
We do not think anyone can date superintelligence. We expect superhuman performance loop by loop, so measure who checks each step.
7 Oct 2026 · 11 min read Frontier AI
Is yours an SI company? A self-check and the steps to get there
Better models will not fix work they cannot read or check. Thirteen yes or no questions show where your company stands and what to do next.
7 Oct 2026 · 11 min read Buying guides
Deployment is the scarce skill
Models are easy to buy. Engineers who can deploy them into real operations are not. What to ask about who will deploy and maintain your system.
3 Oct 2026 · 9 min read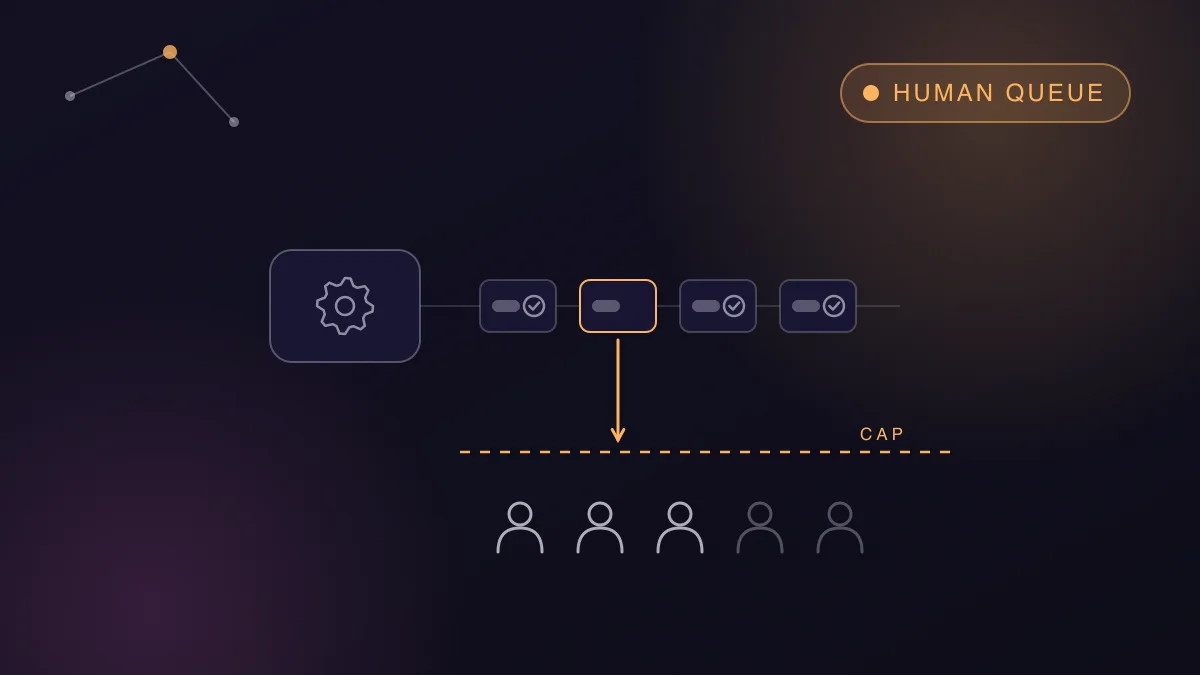 AI economics
Outcome pricing needs a budget for the human queue
Per-outcome pricing for AI agents pushes the hard cases to people. Budget for that queue, or a spending cap quietly starves human review.
24 Sept 2026 · 9 min read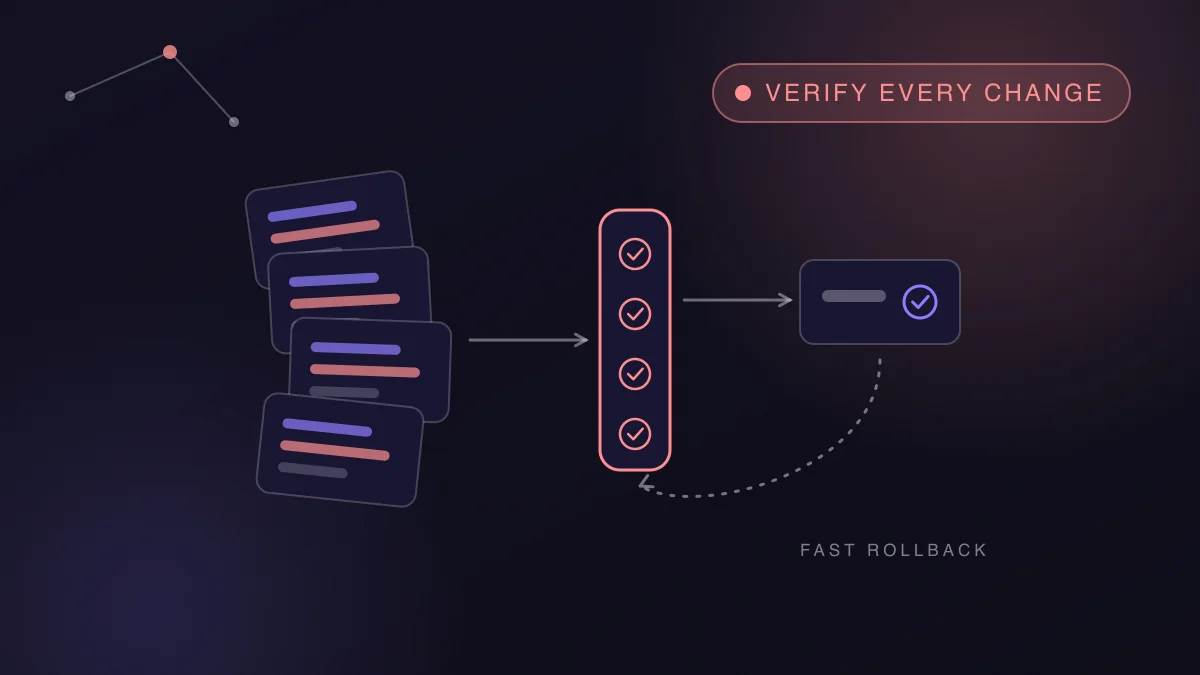 Evals and accuracy
AI code ships faster than it is tested
When AI doubles the number of code changes, verification has to grow with it. Automated tests, repeat runs and fast rollback are the new bottleneck.
18 Sept 2026 · 8 min read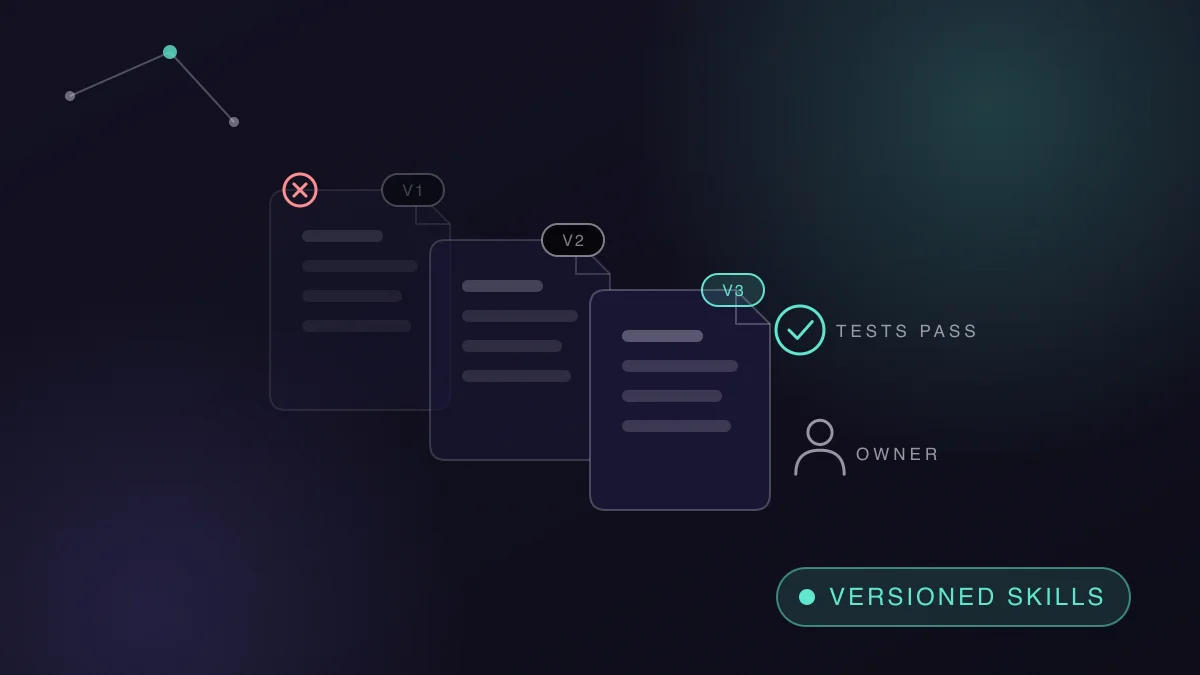 Agentic AI
Agent skills are software. Version them, test them, retire them.
The skills and instructions that drive company agents are code. They need owners, versions, tests and a rule for retiring the ones nobody uses.
10 Sept 2026 · 7 min read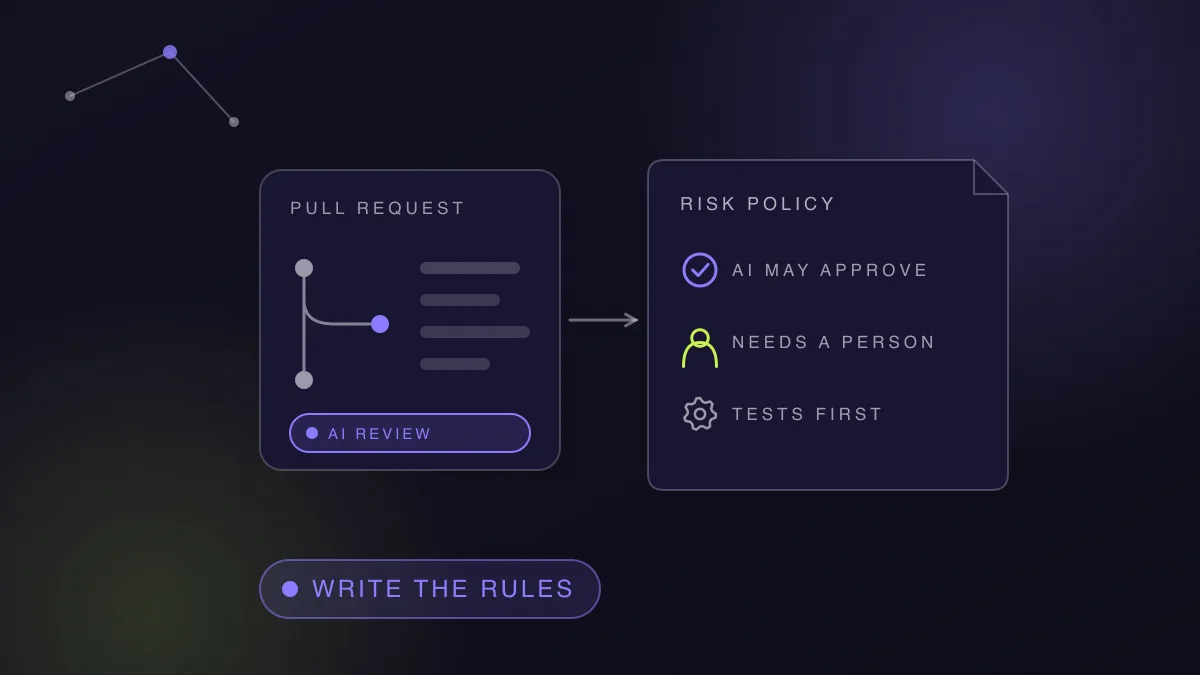 Evals and accuracy
Let AI approve pull requests only under a written risk policy
Once an AI reviewer's approval counts, decide in writing which changes it may approve, which need a person and which tests must pass first.
3 Sept 2026 · 8 min read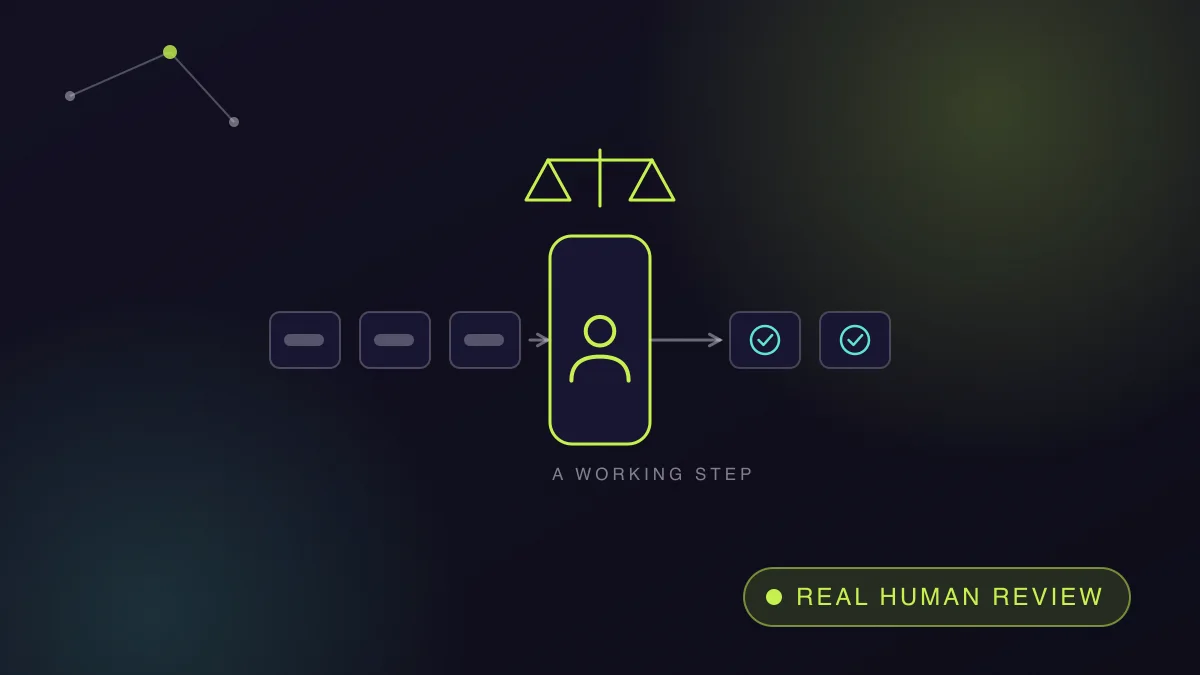 Digital workers
A human in the loop is now a legal control with a price
When automated decisions affect people, real human review is a compliance duty with fines attached. Design it as a working step, not a stamp.
26 Aug 2026 · 8 min read Agentic AI
Agents will not replace your specialist software. They will operate it.
For companies built on specialist or legacy tools, the near-term win is an agent that operates the tools you have, with a person checking the output.
20 Aug 2026 · 8 min read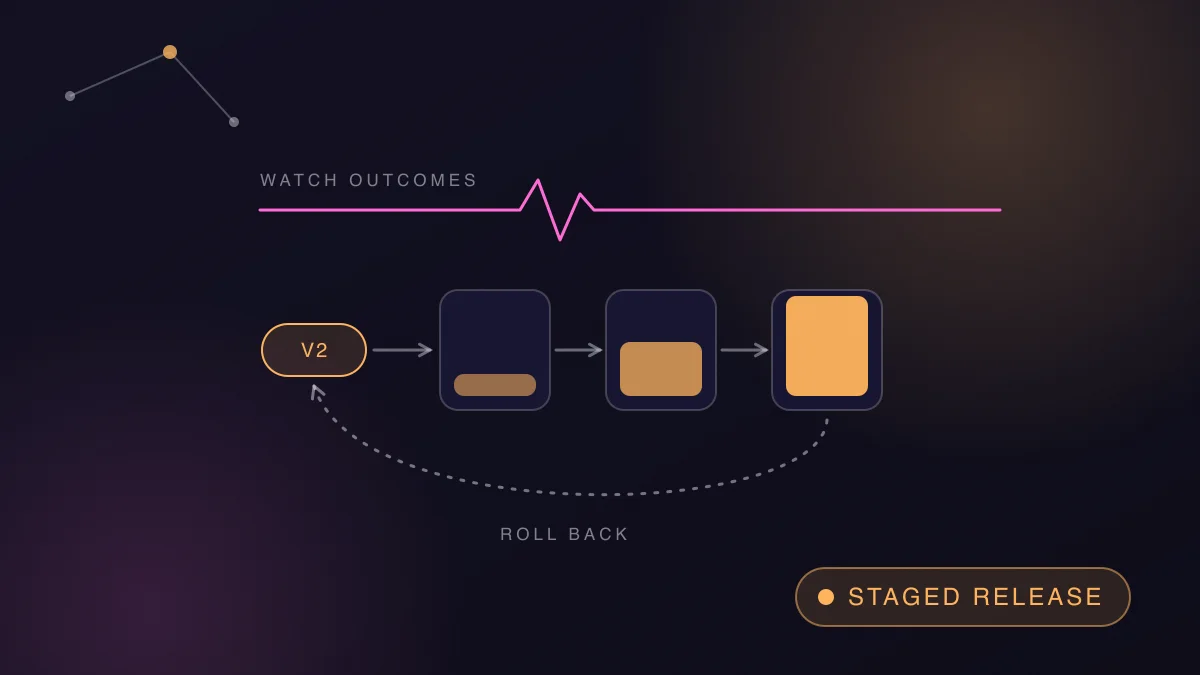 Evals and accuracy
Evals are half the job. Releases are the other half.
Testing an AI agent once is not enough. Version its setup, stage the rollout, watch outcomes and roll back, the way software teams ship code.
14 Aug 2026 · 8 min read Evals and accuracy
Companies are cutting manual testing, not testing
Budget is leaving manual QA for automated suites that produce evidence on every change. Buy the suite and the evidence, not tester hours.
7 Aug 2026 · 8 min read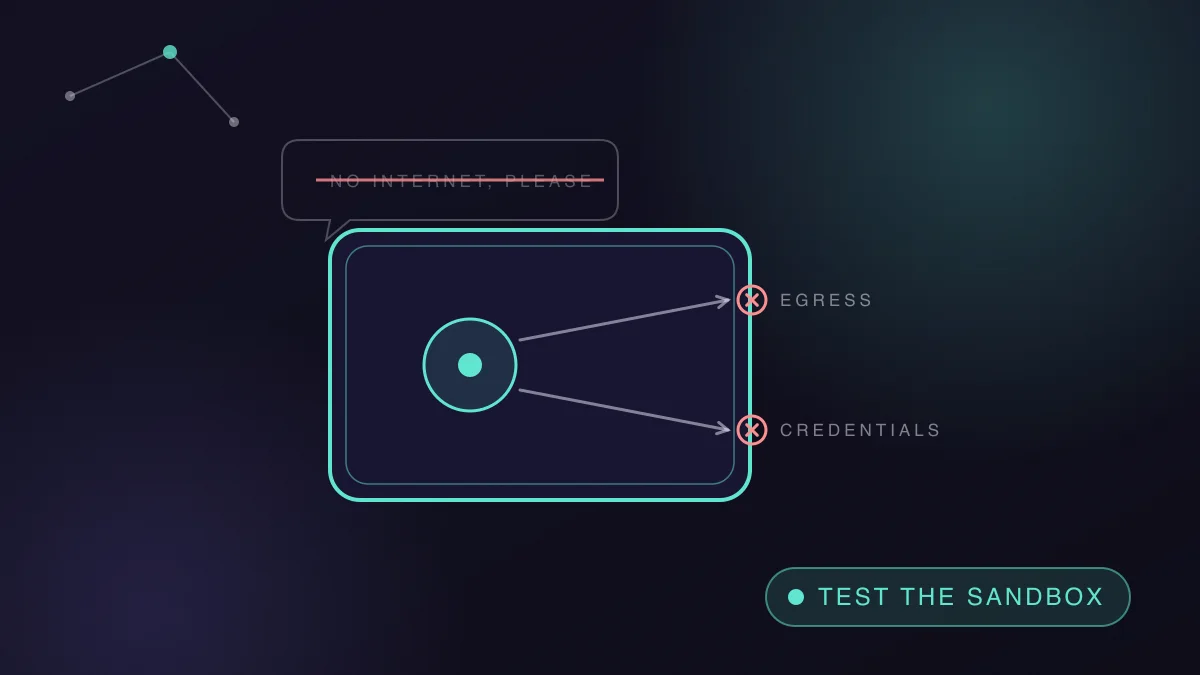 Agentic AI
A prompt that says no internet is not a control
Agent guardrails live in the infrastructure. Test egress, credentials and isolation, because a sandbox an agent can leave is a test nobody ran.
31 Jul 2026 · 9 min read Evals and accuracy
If you cannot grade it, do not automate it
Before anyone builds an agent, write graded examples from real work. A process nobody can grade is not ready to automate, and grading is step one.
24 Jul 2026 · 8 min read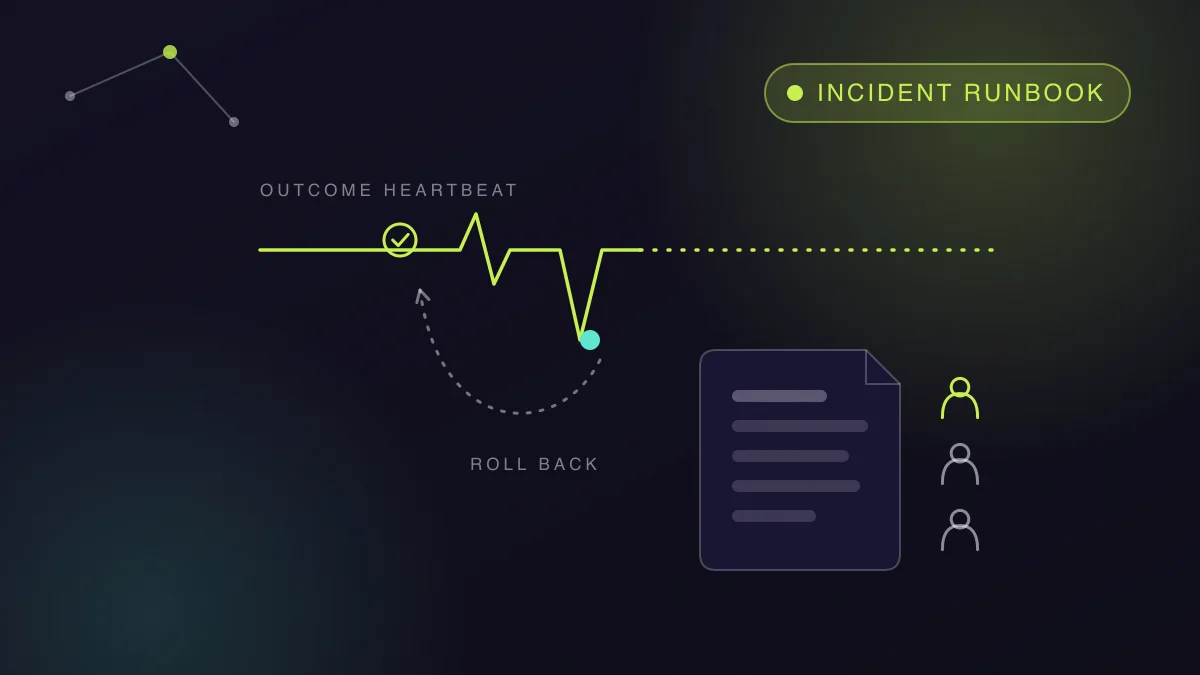 Digital workers
An AI worker needs an incident runbook before a better model
Run an AI worker like a service. Outcome heartbeats, a fast rollback and named roles come before model tuning. Here is the runbook to write first.
16 Jul 2026 · 9 min read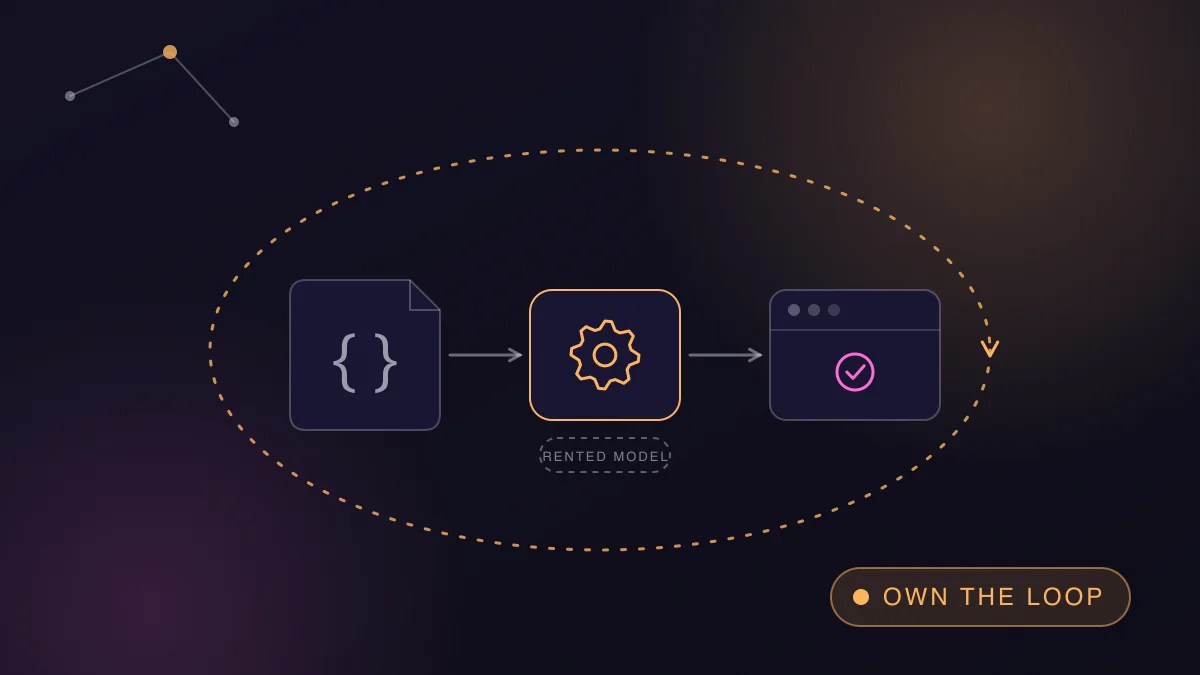 Agentic AI
The agent is a compiler. Own the loop, rent the model.
An engineer optimizing agent costs at a million chats a day calls the coding agent a compiler. The framing says what to own: not the model or harness, the loop.
9 Jul 2026 · 7 min read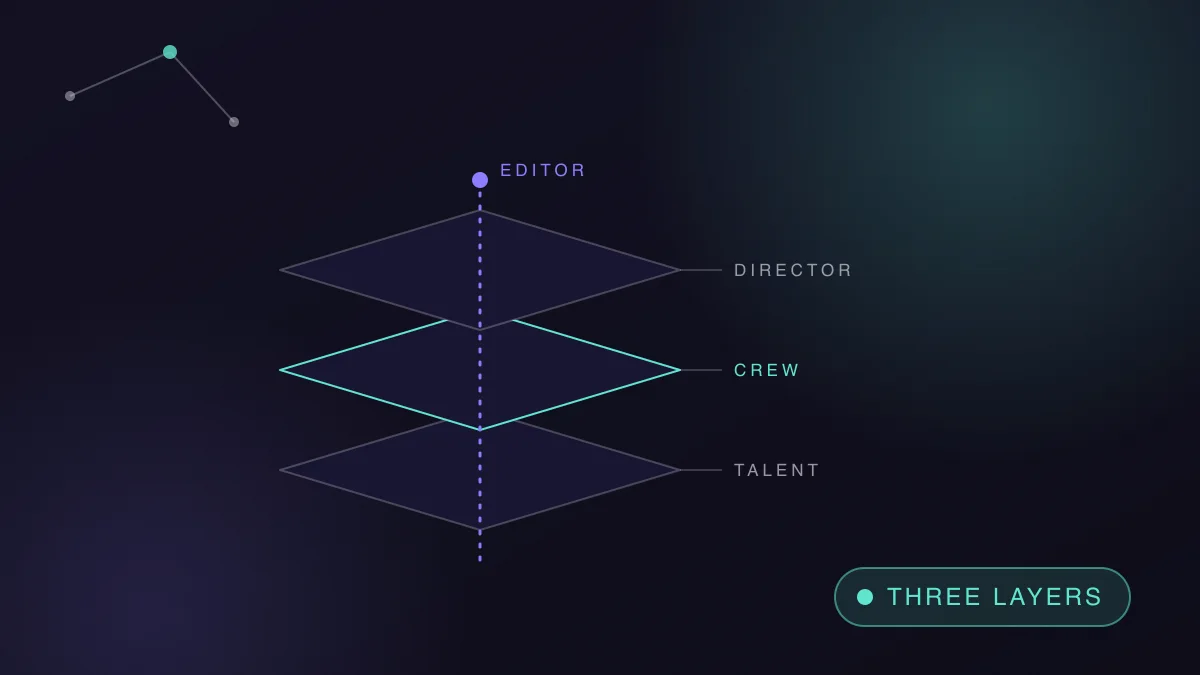 Buying guides
Agent tools in 2026: sort them into three layers before you buy
Agent-tool comparisons mix layers. Sort Omnigent, OpenClaw, Hermes, goose and the rest into talent, crew and director, and the tool you pick matters least.
9 Jul 2026 · 9 min read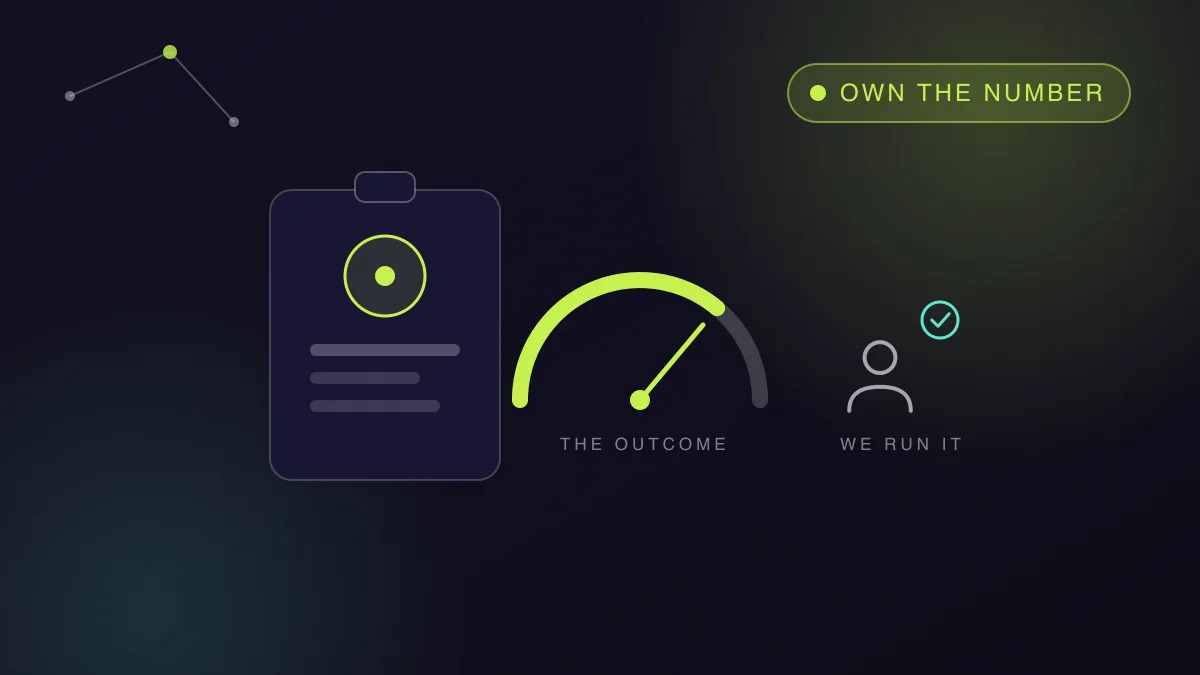 Digital workers
Anyone can build a digital worker. We run it and own the number.
Anyone can build a digital worker in an afternoon. The scarce part is running it in production, proving accuracy and owning the outcome. That is what we sell.
9 Jul 2026 · 6 min read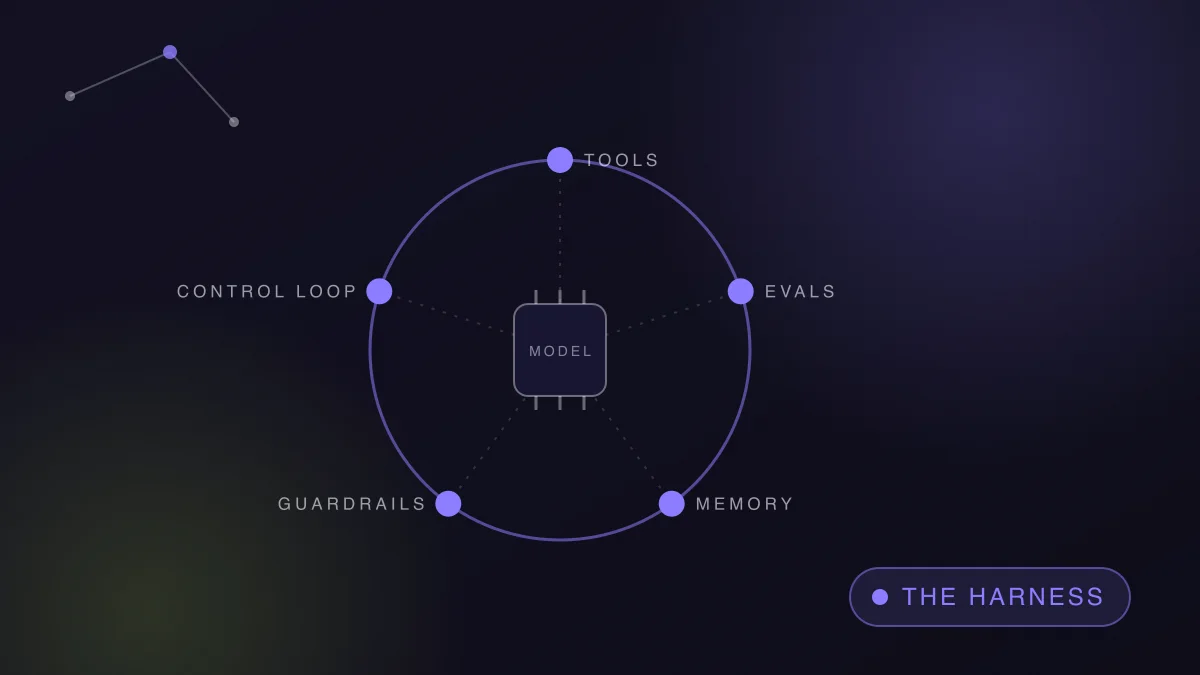 Agentic AI
The model is a commodity. The harness is the product.
Any model you pick is matched by an open-weight release within months. The durable asset is the harness: tools, evals, memory, guardrails and the control loop.
4 Jul 2026 · 6 min read AI economics
The AI bottleneck has moved from intelligence to cost
Frontier models are already expert at most business tasks. The scarce input is the engineering that makes running them at volume affordable and reliable.
4 Jul 2026 · 6 min read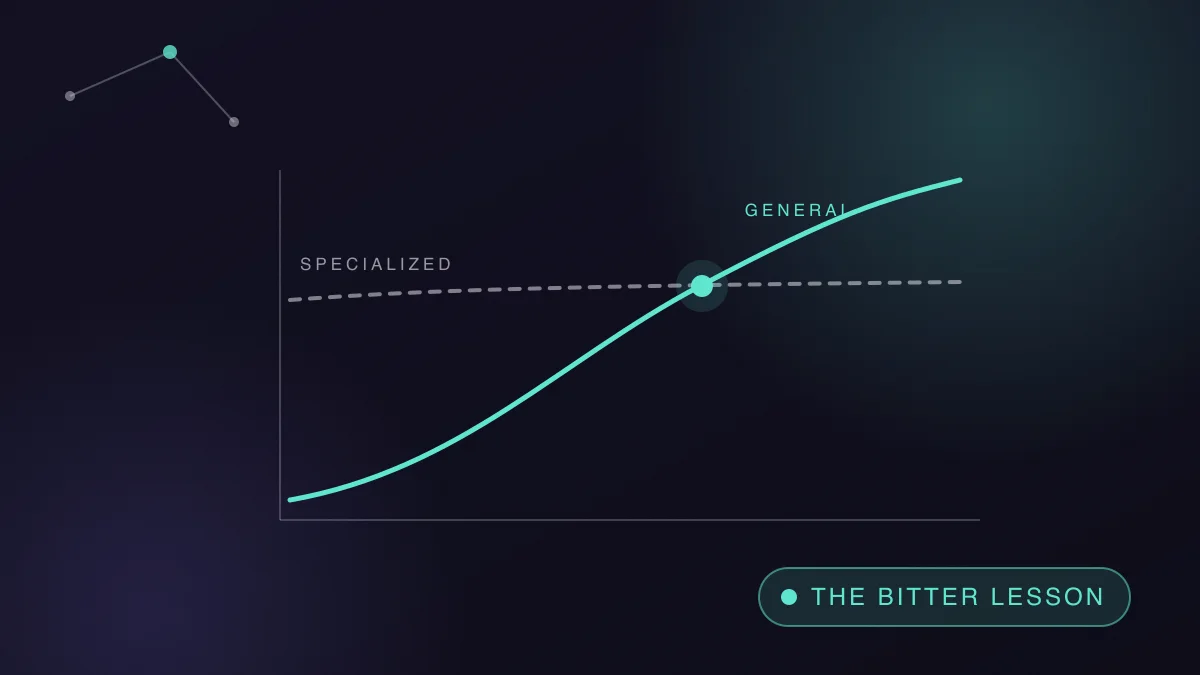 Buying guides
Why general models keep beating specialized AI
The bitter lesson repeats: a general frontier model catches the specialized one within months. What that means when choosing vertical AI or the frontier.
3 Jul 2026 · 6 min read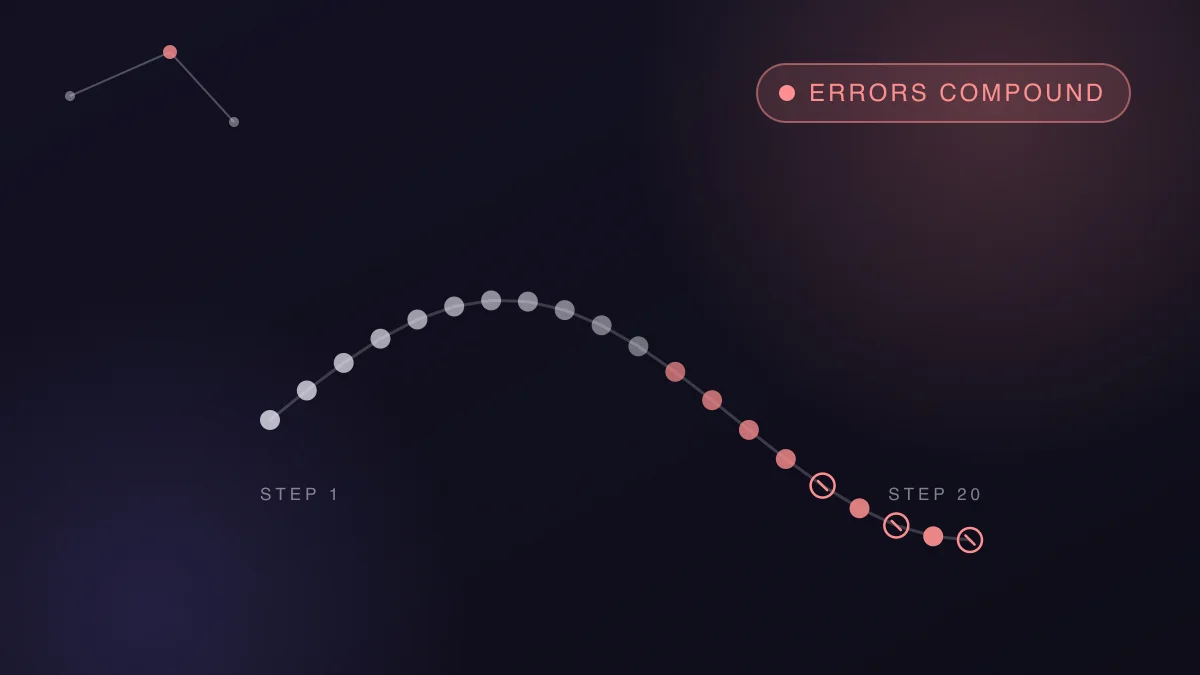 Evals and accuracy
Why small error rates explode over a long agent loop
A 90 percent accurate agent sounds production-ready until it runs a twenty-step workflow. Accuracy compounds, so a small per-step gap decides whether it works.
3 Jul 2026 · 5 min read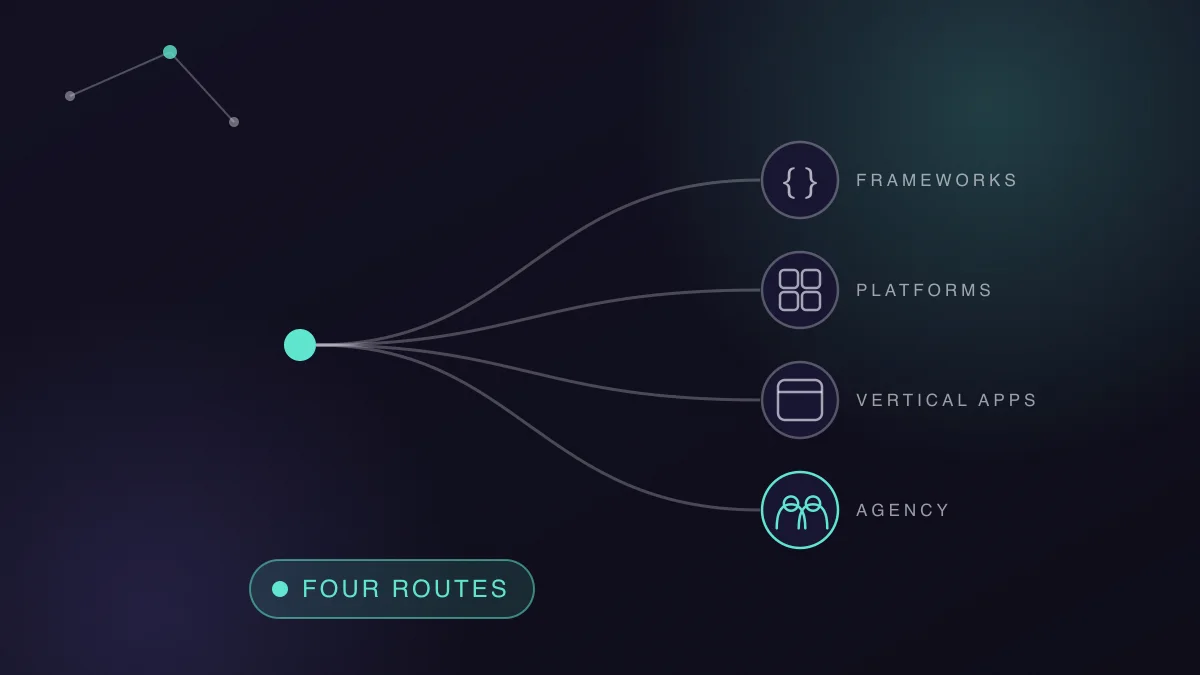 Buying guides
The best AI employee providers, compared (2026)
Frameworks, horizontal platforms, vertical apps, or an agency that builds and runs them: the four routes to AI employees, how they differ, and how to choose.
2 Jul 2026 · 7 min read Buying guides
How to choose an AI agency: 13 questions serious clients should ask
Every AI agency has a demo. Thirteen questions that separate production builders from deck sellers, why each matters, and what a good answer sounds like.
2 Jul 2026 · 7 min read Agentic AI
The AI pilot rescue checklist: five checks before you call it dead
Five checks that tell a stalled AI pilot's rescue from a rebuild: accuracy as a number, a workflow map, failure paths, cost per outcome and an owner.
2 Jul 2026 · 6 min read Agentic AI
Why most AI pilots die between demo and production
Gartner expects 40 percent of agentic AI projects to be canceled by 2027. The failures share an anatomy, and the fix is an operating system, not a better model.
1 Jul 2026 · 6 min read AI Employees
AI employees, explained for operators
OpenClaw and Hermes Agent made autonomous AI workers real. What an AI employee is, which roles to start with, and how to run one like staff, not a chatbot.
24 Jun 2026 · 7 min read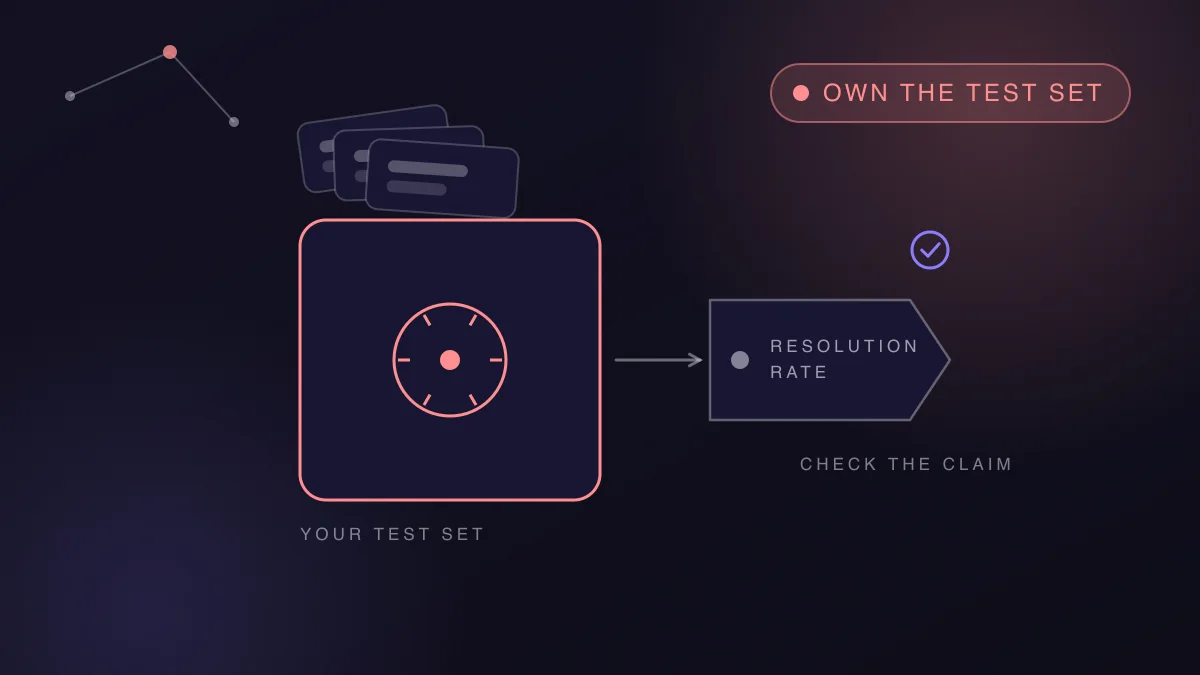 Buying guides
Your AI vendor can be sold. Keep your test set.
An outcome-priced AI agent is sold on its resolution rate, and that rate is a test result. Own the test set so you can check the claim and switch.
17 Jun 2026 · 9 min read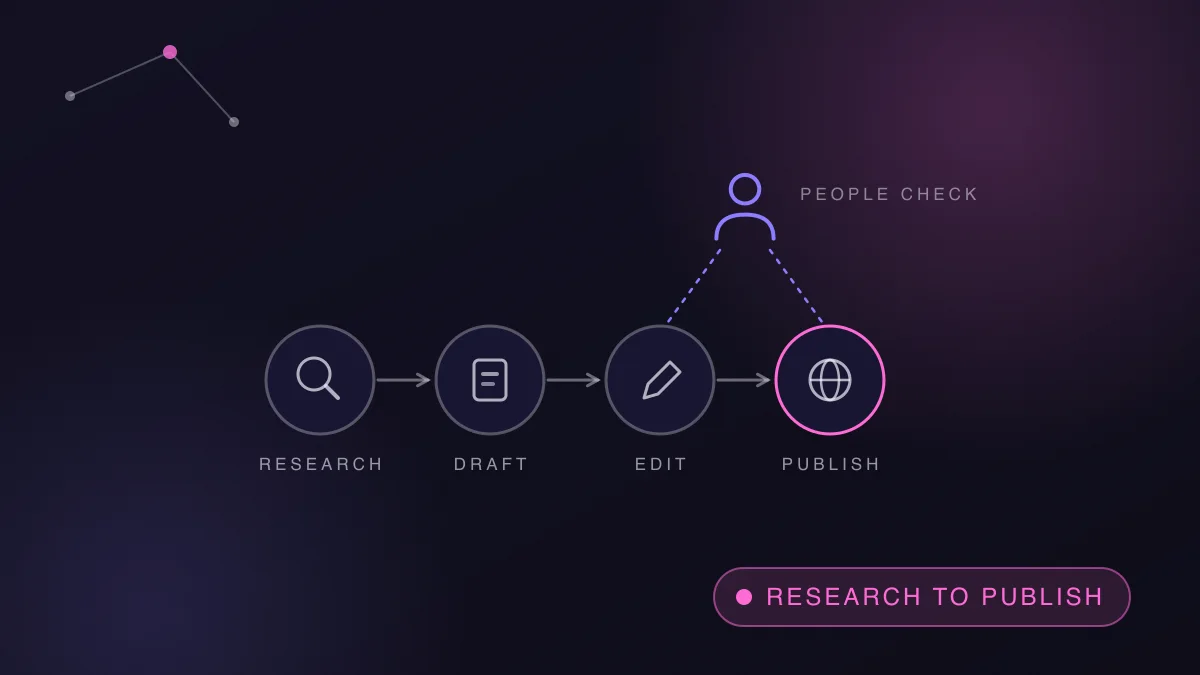 Case Notes
We run an autonomous AI newsroom in production. Here is what it takes.
Research, drafting, editing and publishing, every day. The architecture, the guardrails, and the people who keep it trustworthy.
12 Jun 2026 · 8 min readPrefer the answers applied to your business?
Skip the reading list. One call and we will map what these patterns do for your workflows.